
Featured Functions
Featured Functions
1. Downsampling Functions
1.1 date_bin Function
Description
The date_bin function is a scalar function that aligns timestamps to the start of specified time intervals. It is commonly used with the GROUP BY clause for downsampling.
- Partial Intervals May Be Empty: Only timestamps that meet the conditions are aligned; missing intervals are not filled.
- All Intervals Return Empty: If no data exists within the query range, the downsampling result is an empty set.
Usage Examples
Sample Dataset: The example data page contains SQL statements for building table structures and inserting data. Download and execute these statements in the IoTDB CLI to import the data into IoTDB. You can use this data to test and execute the SQL statements in the examples and obtain the corresponding results.
Example 1: Hourly Average Temperature for Device 100
SELECT date_bin(1h, time) AS hour_time, avg(temperature) AS avg_temp
FROM table1
WHERE (time >= 2024-11-27 00:00:00  AND time <= 2024-11-30 00:00:00)
      AND device_id = '100'
GROUP BY 1;
Result
+-----------------------------+--------+
|                    hour_time|avg_temp|
+-----------------------------+--------+
|2024-11-29T11:00:00.000+08:00|    null|
|2024-11-29T18:00:00.000+08:00|    90.0|
|2024-11-28T08:00:00.000+08:00|    85.0|
|2024-11-28T09:00:00.000+08:00|    null|
|2024-11-28T10:00:00.000+08:00|    85.0|
|2024-11-28T11:00:00.000+08:00|    88.0|
+-----------------------------+--------+
Example 2: Hourly Average Temperature for Each Device
SELECT date_bin(1h, time) AS hour_time, device_id, avg(temperature) AS avg_temp
FROM table1
WHERE time >= 2024-11-27 00:00:00  AND time <= 2024-11-30 00:00:00
GROUP BY 1, device_id;
Result
+-----------------------------+---------+--------+
|                    hour_time|device_id|avg_temp|
+-----------------------------+---------+--------+
|2024-11-29T11:00:00.000+08:00|      100|    null|
|2024-11-29T18:00:00.000+08:00|      100|    90.0|
|2024-11-28T08:00:00.000+08:00|      100|    85.0|
|2024-11-28T09:00:00.000+08:00|      100|    null|
|2024-11-28T10:00:00.000+08:00|      100|    85.0|
|2024-11-28T11:00:00.000+08:00|      100|    88.0|
|2024-11-29T10:00:00.000+08:00|      101|    85.0|
|2024-11-27T16:00:00.000+08:00|      101|    85.0|
+-----------------------------+---------+--------+
Example 3: Hourly Average Temperature for All Devices
SELECT date_bin(1h, time) AS hour_time, avg(temperature) AS avg_temp
  FROM table1
  WHERE time >= 2024-11-27 00:00:00  AND time <= 2024-11-30 00:00:00
  group by 1;
Result
+-----------------------------+--------+
|                    hour_time|avg_temp|
+-----------------------------+--------+
|2024-11-29T10:00:00.000+08:00|    85.0|
|2024-11-27T16:00:00.000+08:00|    85.0|
|2024-11-29T11:00:00.000+08:00|    null|
|2024-11-29T18:00:00.000+08:00|    90.0|
|2024-11-28T08:00:00.000+08:00|    85.0|
|2024-11-28T09:00:00.000+08:00|    null|
|2024-11-28T10:00:00.000+08:00|    85.0|
|2024-11-28T11:00:00.000+08:00|    88.0|
+-----------------------------+--------+
1.2 date_bin_gapfill Function
Description:
The date_bin_gapfill function is an extension of date_bin that fills in missing time intervals, returning a complete time series.
- Partial Intervals May Be Empty: Aligns timestamps for data that meets the conditions and fills in missing intervals.
- All Intervals Return Empty: If no data exists within the query range, the result is an empty set.
Limitations:
- The function must always be used with the
GROUP BYclause. If used elsewhere, it behaves likedate_binwithout gap-filling. - A
GROUP BYclause can contain only one instance of date_bin_gapfill. Multiple calls will result in an error. - The
GAPFILLoperation occurs after theHAVINGclause and before theFILLclause. - The
WHEREclause must include time filters in one of the following forms:time >= XXX AND time <= XXXtime > XXX AND time < XXXtime BETWEEN XXX AND XXX
- If additional time filters or conditions are used, an error is raised. Time conditions and other value filters must be connected using the
ANDoperator. - If
startTimeandendTimecannot be inferred from theWHEREclause, an error is raised.
Usage Examples
Example 1: Fill Missing Intervals
SELECT date_bin_gapfill(1h, time) AS hour_time, avg(temperature) AS avg_temp
FROM table1
WHERE (time >= 2024-11-28 07:00:00  AND time <= 2024-11-28 16:00:00)
      AND device_id = '100'
GROUP BY 1;
Result
+-----------------------------+--------+
|                    hour_time|avg_temp|
+-----------------------------+--------+
|2024-11-28T07:00:00.000+08:00|    null|
|2024-11-28T08:00:00.000+08:00|    85.0|
|2024-11-28T09:00:00.000+08:00|    null|
|2024-11-28T10:00:00.000+08:00|    85.0|
|2024-11-28T11:00:00.000+08:00|    88.0|
|2024-11-28T12:00:00.000+08:00|    null|
|2024-11-28T13:00:00.000+08:00|    null|
|2024-11-28T14:00:00.000+08:00|    null|
|2024-11-28T15:00:00.000+08:00|    null|
|2024-11-28T16:00:00.000+08:00|    null|
+-----------------------------+--------+
Example 2: Fill Missing Intervals with Device Grouping
SELECT date_bin_gapfill(1h, time) AS hour_time, device_id, avg(temperature) AS avg_temp
FROM table1
WHERE time >= 2024-11-28 07:00:00  AND time <= 2024-11-28 16:00:00
GROUP BY 1, device_id;
Result
+-----------------------------+---------+--------+
|                    hour_time|device_id|avg_temp|
+-----------------------------+---------+--------+
|2024-11-28T07:00:00.000+08:00|      100|    null|
|2024-11-28T08:00:00.000+08:00|      100|    85.0|
|2024-11-28T09:00:00.000+08:00|      100|    null|
|2024-11-28T10:00:00.000+08:00|      100|    85.0|
|2024-11-28T11:00:00.000+08:00|      100|    88.0|
|2024-11-28T12:00:00.000+08:00|      100|    null|
|2024-11-28T13:00:00.000+08:00|      100|    null|
|2024-11-28T14:00:00.000+08:00|      100|    null|
|2024-11-28T15:00:00.000+08:00|      100|    null|
|2024-11-28T16:00:00.000+08:00|      100|    null|
+-----------------------------+---------+--------+
Example 3: Empty Result Set for No Data in Range
SELECT date_bin_gapfill(1h, time) AS hour_time, device_id, avg(temperature) AS avg_temp
FROM table1
WHERE time >= 2024-11-27 09:00:00  AND time <= 2024-11-27 14:00:00
GROUP BY 1, device_id;
Result
+---------+---------+--------+
|hour_time|device_id|avg_temp|
+---------+---------+--------+
+---------+---------+--------+
1.3 M4 Function
1.3.1 Description
M4 is a built-in polymorphic table function in the table model for downsampling time-series data. For each window, it extracts the first, last, minimum (bottom), and maximum (top) points to reduce the number of returned points while preserving the shape of the trend. M4 takes a table argument and returns a result table, so it must be called in the FROM clause.
- First point: the point with the earliest timestamp and a non-
NULLvalue in the window. - Last point: the point with the latest timestamp and a non-
NULLvalue in the window. - Minimum and maximum points: the points with the smallest and largest values in the window. If multiple points have the same value, the first point encountered in the input scan order is retained.
- Both time windows and point-count windows are supported. A duration literal for
SIZE, such as1hor10m, selects time-window mode; a positive integer, such as100, selects point-count-window mode.
Supported since V2.0.12.1
1.3.2 Function Definition
SELECT *
FROM M4(
  DATA => input_table PARTITION BY partition_column ORDER BY time_column,
  TIMECOL => 'time_column',
  [ORIGIN => origin_timestamp,]
  SIZE => window_duration | window_point_count,
  [SLIDE => window_duration | window_point_count]
);
DATA is a set-semantic table argument. ORDER BY is required and must contain only the time column specified by TIMECOL, in ascending order. PARTITION BY is optional; if omitted, the entire input table is treated as one partition. Arguments can be passed by name or in declaration order. Named arguments are recommended.
1.3.3 Parameters
| Parameter | Type | Required | Description |
|---|---|---|---|
DATA | Table argument (SET SEMANTIC) | Yes | Input table or subquery. Supports PARTITION BY and ORDER BY. |
TIMECOL | String | Yes | Name of the time column. The column must be of type TIMESTAMP, and ORDER BY must contain only this column. |
ORIGIN | Timestamp | No | Alignment origin for time windows. Defaults to 0. Not used in point-count-window mode. |
SIZE | Duration or INT64 | Yes | Duration of a time window or number of points in a point-count window. Must be positive. |
SLIDE | Same type as SIZE | No | Window sliding step. Defaults to SIZE and must use the same window mode as SIZE. |
Calculation Rules
- The column specified by
TIMECOLis excluded from M4 calculations. - Columns specified by
PARTITION BYare excluded from calculations but retained in the output. - All remaining columns of comparable types participate in M4 calculations.
- After excluding the time and partition columns, analysis fails if no comparable column remains or if any remaining column has a non-comparable type.
- Records with a
NULLvalue in a participating column are excluded from that column'sfirst,last,bottom, andtopcalculations. - For each participating column, the
first,last,bottom, andtoppoints are calculated, deduplicated, and output in ascending timestamp order.
Returned Results
- Time-window mode always generates
window_startandwindow_end, both of typeTIMESTAMP, to represent the interval[window_start, window_end). - Point-count-window mode always generates
window_index, of typeINT64. Window indices are calculated independently within eachPARTITION BYpartition, starting at0. - Partition columns retain their original names and types and appear in declaration order.
OBJECTcolumns cannot be partition columns.BLOBpartition columns can be retained in the output but do not participate in M4 calculations. - For each participating column
c, two output columns are generated:c_timefor the point's timestamp andcfor its value. Their types match the corresponding input types. Results for multiple columns are expanded in input-column order.
The number of output rows in a window equals the largest number of feature points among all participating columns. For columns with fewer feature points, the remaining c_time and c cells are filled with NULL.
1.3.4 Usage Examples
The following examples use table1 from Sample Data. Because table1 contains additional columns besides the time and partition columns, a subquery selects only time, device_id, temperature, and humidity for M4 calculations.
Example 1: Time Windows
For device_id = '101', divide the data into 3-minute windows. SIZE => 3m selects time-window mode with a duration of 3 minutes. Each half-open interval [window_start, window_end) extracts the first, last, minimum, and maximum points for temperature and humidity, then outputs the points in ascending timestamp order.
SELECT window_start,
       window_end,
       device_id,
       temperature_time,
       temperature,
       humidity_time,
       humidity
FROM M4(
  DATA => (
    SELECT time, device_id, temperature, humidity
    FROM table1
    WHERE device_id = '101'
      AND time >= 2024-11-27 16:38:00
      AND time <= 2024-11-27 16:44:00
  ) PARTITION BY device_id ORDER BY time,
  TIMECOL => 'time',
  SIZE => 3m
);
Result:
+-----------------------------+-----------------------------+---------+-----------------------------+-----------+-----------------------------+--------+
|                 window_start|                   window_end|device_id|             temperature_time|temperature|                humidity_time|humidity|
+-----------------------------+-----------------------------+---------+-----------------------------+-----------+-----------------------------+--------+
|2024-11-27T16:36:00.000+08:00|2024-11-27T16:39:00.000+08:00|      101|                         null|       null|2024-11-27T16:38:00.000+08:00|    35.1|
|2024-11-27T16:39:00.000+08:00|2024-11-27T16:42:00.000+08:00|      101|2024-11-27T16:39:00.000+08:00|       85.0|2024-11-27T16:39:00.000+08:00|    35.3|
|2024-11-27T16:39:00.000+08:00|2024-11-27T16:42:00.000+08:00|      101|2024-11-27T16:41:00.000+08:00|       85.0|                         null|    null|
|2024-11-27T16:42:00.000+08:00|2024-11-27T16:45:00.000+08:00|      101|                         null|       null|2024-11-27T16:42:00.000+08:00|    35.2|
+-----------------------------+-----------------------------+---------+-----------------------------+-----------+-----------------------------+--------+
Example 2: Point-Count Windows
For device_id = '101', divide the data into windows of 3 points. SIZE => 3 selects point-count-window mode, with 3 input rows per window. window_index identifies each window and starts at 0 within each partition.
SELECT window_index,
       device_id,
       temperature_time,
       temperature,
       humidity_time,
       humidity
FROM M4(
  DATA => (
    SELECT time, device_id, temperature, humidity
    FROM table1
    WHERE device_id = '101'
      AND time >= 2024-11-27 16:38:00
      AND time <= 2024-11-27 16:44:00
  ) PARTITION BY device_id ORDER BY time,
  TIMECOL => 'time',
  SIZE => 3
);
Result:
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
|window_index|device_id|             temperature_time|temperature|                humidity_time|humidity|
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
|           0|      101|2024-11-27T16:39:00.000+08:00|       85.0|2024-11-27T16:38:00.000+08:00|    35.1|
|           0|      101|2024-11-27T16:40:00.000+08:00|       85.0|2024-11-27T16:39:00.000+08:00|    35.3|
|           1|      101|2024-11-27T16:41:00.000+08:00|       85.0|2024-11-27T16:42:00.000+08:00|    35.2|
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
To specify the sliding step, also set SLIDE:
SELECT window_index,
       device_id,
       temperature_time,
       temperature,
       humidity_time,
       humidity
FROM M4(
  DATA => (
    SELECT time, device_id, temperature, humidity
    FROM table1
    WHERE device_id = '101'
      AND time >= 2024-11-27 16:38:00
      AND time <= 2024-11-27 16:44:00
  ) PARTITION BY device_id ORDER BY time,
  TIMECOL => 'time',
  SIZE => 3,
  SLIDE => 2
);
This call uses a window size of 3 points and advances the window by 2 points each time.
Result:
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
|window_index|device_id|             temperature_time|temperature|                humidity_time|humidity|
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
|           0|      101|2024-11-27T16:39:00.000+08:00|       85.0|2024-11-27T16:38:00.000+08:00|    35.1|
|           0|      101|2024-11-27T16:40:00.000+08:00|       85.0|2024-11-27T16:39:00.000+08:00|    35.3|
|           1|      101|2024-11-27T16:40:00.000+08:00|       85.0|2024-11-27T16:42:00.000+08:00|    35.2|
|           1|      101|2024-11-27T16:41:00.000+08:00|       85.0|                         null|    null|
|           2|      101|                         null|       null|2024-11-27T16:42:00.000+08:00|    35.2|
+------------+---------+-----------------------------+-----------+-----------------------------+--------+
Example 3: Invalid Sort Column
M4 requires ORDER BY on the DATA argument, and the sort column must match the time column specified by TIMECOL. The following example incorrectly sorts by temperature:
SELECT *
FROM M4(
  DATA => (
    SELECT time, device_id, temperature, humidity
    FROM table1
    WHERE device_id = '101'
  ) PARTITION BY device_id ORDER BY temperature,
  TIMECOL => 'time',
  SIZE => 3m
);
Error:
Msg: org.apache.iotdb.jdbc.IoTDBSQLException: 701: The ORDER BY clause of the DATA argument must contain exactly the time column specified by the TIMECOL argument.2. DIFF Function
2.1 Description:
- The
DIFFfunction calculates the difference between the current row and the previous row. For the first row, it returnsNULLsince there is no previous row.
2.2 Function Definition:
DIFF(numberic[, boolean]) -> Double2.3 Parameters:
First Parameter (numeric):
- Type: Must be numeric (
INT32,INT64,FLOAT,DOUBLE). - Purpose: Specifies the column for which to calculate the difference.
Second Parameter (boolean, optional):
- Type: Boolean (
trueorfalse). - Default:
true. - Purpose:
true: IgnoresNULLvalues and uses the first non-NULLvalue for calculation. If no non-NULLvalue exists, returnsNULL.false: Does not ignoreNULLvalues. If the previous row isNULL, the result isNULL.
2.4 Notes:
- In tree models, the second parameter must be specified as
'ignoreNull'='true'or'ignoreNull'='false'. - In table models, simply use
trueorfalse. Using'ignoreNull'='true'or'ignoreNull'='false'in table models results in a string comparison and always evaluates tofalse.
2.5 Usage Examples
Example 1: Ignore NULL Values
SELECT time, DIFF(temperature) AS diff_temp
FROM table1
WHERE device_id = '100';
Result
+-----------------------------+---------+
|                         time|diff_temp|
+-----------------------------+---------+
|2024-11-29T11:00:00.000+08:00|     null|
|2024-11-29T18:30:00.000+08:00|     null|
|2024-11-28T08:00:00.000+08:00|     -5.0|
|2024-11-28T09:00:00.000+08:00|     null|
|2024-11-28T10:00:00.000+08:00|      0.0|
|2024-11-28T11:00:00.000+08:00|      3.0|
|2024-11-26T13:37:00.000+08:00|      2.0|
|2024-11-26T13:38:00.000+08:00|      0.0|
+-----------------------------+---------+
Example 2: Do Not Ignore NULL Values
SELECT time, DIFF(temperature, false) AS diff_temp
FROM table1
WHERE device_id = '100';
Result
+-----------------------------+---------+
|                         time|diff_temp|
+-----------------------------+---------+
|2024-11-29T11:00:00.000+08:00|     null|
|2024-11-29T18:30:00.000+08:00|     null|
|2024-11-28T08:00:00.000+08:00|     -5.0|
|2024-11-28T09:00:00.000+08:00|     null|
|2024-11-28T10:00:00.000+08:00|     null|
|2024-11-28T11:00:00.000+08:00|      3.0|
|2024-11-26T13:37:00.000+08:00|      2.0|
|2024-11-26T13:38:00.000+08:00|      0.0|
+-----------------------------+---------+
Example 3: Full Example
SELECT time, temperature,
       DIFF(temperature) AS diff_temp_1,
       DIFF(temperature, false) AS diff_temp_2
FROM table1
WHERE device_id = '100';
Result
+-----------------------------+-----------+-----------+-----------+
|                         time|temperature|diff_temp_1|diff_temp_2|
+-----------------------------+-----------+-----------+-----------+
|2024-11-29T11:00:00.000+08:00|       null|       null|       null|
|2024-11-29T18:30:00.000+08:00|       90.0|       null|       null|
|2024-11-28T08:00:00.000+08:00|       85.0|       -5.0|       -5.0|
|2024-11-28T09:00:00.000+08:00|       null|       null|       null|
|2024-11-28T10:00:00.000+08:00|       85.0|        0.0|       null|
|2024-11-28T11:00:00.000+08:00|       88.0|        3.0|        3.0|
|2024-11-26T13:37:00.000+08:00|       90.0|        2.0|        2.0|
|2024-11-26T13:38:00.000+08:00|       90.0|        0.0|        0.0|
+-----------------------------+-----------+-----------+-----------+
3 Timeseries Windowing Functions
The sample data is as follows:
IoTDB> SELECT * FROM bid;
+-----------------------------+--------+-----+
|                         time|stock_id|price|
+-----------------------------+--------+-----+
|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
+-----------------------------+--------+-----+

-- Create table statement
CREATE TABLE bid(time TIMESTAMP TIME, stock_id STRING TAG, price FLOAT FIELD);
-- Insert data
INSERT INTO bid(time, stock_id, price) VALUES('2021-01-01T09:05:00','AAPL',100.0),('2021-01-01T09:06:00','TESL',200.0),('2021-01-01T09:07:00','AAPL',103.0),('2021-01-01T09:07:00','TESL',202.0),('2021-01-01T09:09:00','AAPL',102.0),('2021-01-01T09:15:00','TESL',195.0);
3.1 HOP
Function Description
The HOP function segments data into overlapping time windows for analysis, assigning each row to all windows that overlap with its timestamp. If windows overlap (when SLIDE < SIZE), data will be duplicated across multiple windows.
Function Definition
HOP(data, timecol, size, slide[, origin])Parameter Description
| Parameter | Type | Attributes | Description |
|---|---|---|---|
| DATA | Table | ROW SEMANTIC, PASS THROUGH | Input table |
| TIMECOL | Scalar | String (default: 'time') | Time column |
| SIZE | Scalar | Long integer | Window size |
| SLIDE | Scalar | Long integer | Sliding step |
| ORIGIN | Scalar | Timestamp (default: Unix epoch) | First window start time |
Returned Results
The HOP function returns:
window_start: Window start time (inclusive)window_end: Window end time (exclusive)- Pass-through columns: All input columns from DATA
Usage Example
IoTDB> SELECT * FROM HOP(DATA => bid,TIMECOL => 'time',SLIDE => 5m,SIZE => 10m);
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|                 window_start|                   window_end|                         time|stock_id|price|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:25:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+

-- Equivalent to tree model's GROUP BY TIME when combined with GROUP BY
IoTDB> SELECT window_start, window_end, stock_id, avg(price) as avg FROM HOP(DATA => bid,TIMECOL => 'time',SLIDE => 5m,SIZE => 10m) GROUP BY window_start, window_end, stock_id;
+-----------------------------+-----------------------------+--------+------------------+
|                 window_start|                   window_end|stock_id|               avg|
+-----------------------------+-----------------------------+--------+------------------+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:25:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    AAPL|101.66666666666667|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:15:00.000+08:00|    AAPL|101.66666666666667|
+-----------------------------+-----------------------------+--------+------------------+
3.2 SESSION
Function Description
The SESSION function groups data into sessions based on time intervals. It checks the time gap between consecutive rows—rows with gaps smaller than the threshold (GAP) are grouped into the current window, while larger gaps trigger a new window.
Function Definition
SESSION(data [PARTITION BY(pkeys, ...)] [ORDER BY(okeys, ...)], timecol, gap)Parameter Description
| Parameter | Type | Attributes | Description |
|---|---|---|---|
| DATA | Table | SET SEMANTIC, PASS THROUGH | Input table with partition/sort keys |
| TIMECOL | Scalar | String (default: 'time') | Time column name |
| GAP | Scalar | Long integer | Session gap threshold |
Returned Results
The SESSION function returns:
window_start: Time of the first row in the sessionwindow_end: Time of the last row in the session- Pass-through columns: All input columns from DATA
Usage Example
IoTDB> SELECT * FROM SESSION(DATA => bid PARTITION BY stock_id ORDER BY time,TIMECOL => 'time',GAP => 2m);
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|                 window_start|                   window_end|                         time|stock_id|price|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:06:00.000+08:00|2021-01-01T09:07:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:06:00.000+08:00|2021-01-01T09:07:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:15:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:09:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:09:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:09:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+

-- Equivalent to tree model's GROUP BY SESSION when combined with GROUP BY
IoTDB> SELECT window_start, window_end, stock_id, avg(price) as avg FROM SESSION(DATA => bid PARTITION BY stock_id ORDER BY time,TIMECOL => 'time',GAP => 2m) GROUP BY window_start, window_end, stock_id;
+-----------------------------+-----------------------------+--------+------------------+
|                 window_start|                   window_end|stock_id|               avg|
+-----------------------------+-----------------------------+--------+------------------+
|2021-01-01T09:06:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|101.66666666666667|
+-----------------------------+-----------------------------+--------+------------------+
3.3 VARIATION
Function Description
The VARIATION function groups data based on value differences. The first row becomes the baseline for the first window. Subsequent rows are compared to the baseline—if the difference is within the threshold (DELTA), they join the current window; otherwise, a new window starts with that row as the new baseline.
Function Definition
VARIATION(data [PARTITION BY(pkeys, ...)] [ORDER BY(okeys, ...)], col, delta)Parameter Description
| Parameter | Type | Attributes | Description |
|---|---|---|---|
| DATA | Table | SET SEMANTIC, PASS THROUGH | Input table with partition/sort keys |
| COL | Scalar | String | Column for difference calculation |
| DELTA | Scalar | Float | Difference threshold |
Returned Results
The VARIATION function returns:
window_index: Window identifier- Pass-through columns: All input columns from DATA
Usage Example
IoTDB> SELECT * FROM VARIATION(DATA => bid PARTITION BY stock_id ORDER BY time,COL => 'price',DELTA => 2.0);
+------------+-----------------------------+--------+-----+
|window_index|                         time|stock_id|price|
+------------+-----------------------------+--------+-----+
|           0|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|           0|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|           1|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|           0|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|           1|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|           1|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+------------+-----------------------------+--------+-----+

-- Equivalent to tree model's GROUP BY VARIATION when combined with GROUP BY
IoTDB> SELECT first(time) as window_start, last(time) as window_end, stock_id, avg(price) as avg FROM VARIATION(DATA => bid PARTITION BY stock_id ORDER BY time,COL => 'price', DELTA => 2.0) GROUP BY window_index, stock_id;
+-----------------------------+-----------------------------+--------+-----+
|                 window_start|                   window_end|stock_id|  avg|
+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:06:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|201.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:07:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.5|
+-----------------------------+-----------------------------+--------+-----+
3.4 CAPACITY
Function Description
CAPACITY divides data into windows by point count (row count), with at most SIZE rows per window. Since V2.0.12.1, the optional SLIDE argument specifies the number of rows between the start positions of adjacent windows.
Function Definition
CAPACITY(
  DATA => <table_or_query>
    [PARTITION BY <partition_expression> [, ...]]
    [ORDER BY <sort_item> [, ...]],
  SIZE => <positive_int64>
  [, SLIDE => <positive_int64>]
)
Parameter Description
| Parameter | Type | Required | Description |
|---|---|---|---|
DATA | Table | Yes | Input table or subquery. Supports PARTITION BY and ORDER BY and passes through input columns. |
SIZE | INT64 scalar | Yes | Window capacity. Must be positive and specifies the maximum number of rows in a window. |
SLIDE | INT64 scalar | No | Window sliding step. Must be positive when specified. Defaults to SIZE when omitted. |
- With
PARTITION BY, row numbers and window indices are calculated independently within each partition, starting at0. - With
ORDER BY, row numbers follow the specified sort order. - Window indices start at
0. Windowkcovers the row-number interval[k * SLIDE, k * SLIDE + SIZE). - Window behavior depends on the relationship between
SLIDEandSIZE:
| Relationship | Window Type | Behavior |
|---|---|---|
SLIDE < SIZE | Overlapping windows | Adjacent windows overlap. An input row can belong to multiple windows and appear multiple times with different window_index values. |
SLIDE = SIZE | Non-overlapping windows | Adjacent windows are contiguous. This matches the behavior of CAPACITY(DATA => ..., SIZE => n) in earlier versions. |
SLIDE > SIZE | Gapped windows | Gaps exist between adjacent windows. Input rows that fall into a gap are omitted from the output. |
Returned Results
CAPACITY returns the following columns:
window_index: window index of typeINT64, starting at0.- Columns passed through from
DATA, with their original names and types.
You can query the result directly or aggregate it by window_index and business grouping columns.
Usage Example
IoTDB> SELECT * FROM CAPACITY(DATA => bid PARTITION BY stock_id ORDER BY time, SIZE => 2);
+------------+-----------------------------+--------+-----+
|window_index|                         time|stock_id|price|
+------------+-----------------------------+--------+-----+
|           0|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|           0|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|           1|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|           0|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|           0|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|           1|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+------------+-----------------------------+--------+-----+

-- Combine with GROUP BY, equivalent to GROUP BY COUNT in the tree model
IoTDB> SELECT first(time) as start_time, last(time) as end_time, stock_id, avg(price) as avg FROM CAPACITY(DATA => bid PARTITION BY stock_id ORDER BY time, SIZE => 2) GROUP BY window_index, stock_id;
+-----------------------------+-----------------------------+--------+-----+
|                   start_time|                     end_time|stock_id|  avg|
+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:06:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|201.0|
|2021-01-01T09:15:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:05:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|101.5|
|2021-01-01T09:09:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+-----------------------------+-----------------------------+--------+-----+

-- Use SLIDE to generate overlapping windows (SLIDE < SIZE)
TimechoDB> SELECT * FROM CAPACITY(DATA => bid PARTITION BY stock_id ORDER BY time, SIZE => 2, SLIDE => 1);
+------------+-----------------------------+--------+-----+
|window_index|                         time|stock_id|price|
+------------+-----------------------------+--------+-----+
|           0|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|           0|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|           1|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|           1|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
|           2|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
|           0|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|           0|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|           1|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|           1|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|           2|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
+------------+-----------------------------+--------+-----+
3.5 TUMBLE
Function Description
The TUMBLE function assigns each row to a non-overlapping, fixed-size time window based on a timestamp attribute.
Function Definition
TUMBLE(data, timecol, size[, origin])Parameter Description
| Parameter | Type | Attributes | Description |
|---|---|---|---|
| DATA | Table | ROW SEMANTIC, PASS THROUGH | Input table |
| TIMECOL | Scalar | String (default: 'time') | Time column |
| SIZE | Scalar | Long integer (positive) | Window size |
| ORIGIN | Scalar | Timestamp (default: Unix epoch) | First window start time |
Returned Results
The TUMBLE function returns:
window_start: Window start time (inclusive)window_end: Window end time (exclusive)- Pass-through columns: All input columns from DATA
Usage Example
IoTDB> SELECT * FROM TUMBLE( DATA => bid, TIMECOL => 'time', SIZE => 10m);
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|                 window_start|                   window_end|                         time|stock_id|price|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+

-- Equivalent to tree model's GROUP BY TIME when combined with GROUP BY
IoTDB> SELECT window_start, window_end, stock_id, avg(price) as avg FROM TUMBLE(DATA => bid, TIMECOL => 'time', SIZE => 10m) GROUP BY window_start, window_end, stock_id;
+-----------------------------+-----------------------------+--------+------------------+
|                 window_start|                   window_end|stock_id|               avg|
+-----------------------------+-----------------------------+--------+------------------+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    AAPL|101.66666666666667|
+-----------------------------+-----------------------------+--------+------------------+
3.6 CUMULATE
Function Description
The CUMULATE function creates expanding windows from an initial window, maintaining the same start time while incrementally extending the end time by STEP until reaching SIZE. Each window contains all elements within its range. For example, with a 1-hour STEP and 24-hour SIZE, daily windows would be: [00:00, 01:00), [00:00, 02:00), ..., [00:00, 24:00).
Function Definition
CUMULATE(data, timecol, size, step[, origin])Parameter Description
| Parameter | Type | Attributes | Description |
|---|---|---|---|
| DATA | Table | ROW SEMANTIC, PASS THROUGH | Input table |
| TIMECOL | Scalar | String (default: 'time') | Time column |
| SIZE | Scalar | Long integer (positive) | Window size (must be an integer multiple of STEP) |
| STEP | Scalar | Long integer (positive) | Expansion step |
| ORIGIN | Scalar | Timestamp (default: Unix epoch) | First window start time |
Note: An error
Cumulative table function requires size must be an integral multiple of stepoccurs if SIZE is not divisible by STEP.
Returned Results
The CUMULATE function returns:
window_start: Window start time (inclusive)window_end: Window end time (exclusive)- Pass-through columns: All input columns from DATA
Usage Example
IoTDB> SELECT * FROM CUMULATE(DATA => bid,TIMECOL => 'time',STEP => 2m,SIZE => 10m);
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|                 window_start|                   window_end|                         time|stock_id|price|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:06:00.000+08:00|    TESL|200.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    TESL|202.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:16:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:18:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|2021-01-01T09:15:00.000+08:00|    TESL|195.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:06:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:05:00.000+08:00|    AAPL|100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:07:00.000+08:00|    AAPL|103.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|2021-01-01T09:09:00.000+08:00|    AAPL|102.0|
+-----------------------------+-----------------------------+-----------------------------+--------+-----+

-- Equivalent to tree model's GROUP BY TIME when combined with GROUP BY
IoTDB> SELECT window_start, window_end, stock_id, avg(price) as avg FROM CUMULATE(DATA => bid,TIMECOL => 'time',STEP => 2m, SIZE => 10m) GROUP BY window_start, window_end, stock_id;
+-----------------------------+-----------------------------+--------+------------------+
|                 window_start|                   window_end|stock_id|               avg|
+-----------------------------+-----------------------------+--------+------------------+
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    TESL|             201.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:16:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:18:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:10:00.000+08:00|2021-01-01T09:20:00.000+08:00|    TESL|             195.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:06:00.000+08:00|    AAPL|             100.0|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:08:00.000+08:00|    AAPL|             101.5|
|2021-01-01T09:00:00.000+08:00|2021-01-01T09:10:00.000+08:00|    AAPL|101.66666666666667|
+-----------------------------+-----------------------------+--------+------------------+
4. Window Functions
4.1 SQL Definition
windowDefinition
    : name=identifier AS '(' windowSpecification ')'
    ;

windowSpecification
    : (existingWindowName=identifier)?
      (PARTITION BY partition+=expression (',' partition+=expression)*)?
      (ORDER BY sortItem (',' sortItem)*)?
      windowFrame?
    ;

windowFrame
    : frameExtent
    ;

frameExtent
    : frameType=RANGE start=frameBound
    | frameType=ROWS start=frameBound
    | frameType=GROUPS start=frameBound
    | frameType=RANGE BETWEEN start=frameBound AND end=frameBound
    | frameType=ROWS BETWEEN start=frameBound AND end=frameBound
    | frameType=GROUPS BETWEEN start=frameBound AND end=frameBound
    ;

frameBound
    : UNBOUNDED boundType=PRECEDING                 #unboundedFrame
    | UNBOUNDED boundType=FOLLOWING                 #unboundedFrame
    | CURRENT ROW                                   #currentRowBound
    | expression boundType=(PRECEDING | FOLLOWING)  #boundedFrame
    ;
For more detailed introductions to the features, please refer to: Window Function
4.2 Usage Examples
The original data of the device_flow table is as follows:
+-----------------------------+------+-----+
|                         time|device| flow|
+-----------------------------+------+-----+
|1970-01-01T08:00:00.000+08:00|    d0|    3|
|1970-01-01T08:00:00.001+08:00|    d0|    5|
|1970-01-01T08:00:00.002+08:00|    d0|    3|
|1970-01-01T08:00:00.003+08:00|    d0|    1|
|1970-01-01T08:00:00.004+08:00|    d1|    2|
|1970-01-01T08:00:00.005+08:00|    d1|    4|
+-----------------------------+------+-----+- Query all columns from device_flow, group the data by the device dimension, sort the records within each device group by the value of the flow field, calculate the cumulative sum of the flow field, and finally return the cumulative sum as a column named sum.
SQL:
IoTDB> SELECT *, sum(flow) OVER (PARTITION BY device ORDER BY flow) as sum FROM device_flow;Result:
+-----------------------------+------+----+----+
|                         time|device|flow| sum|
+-----------------------------+------+----+----+
|1970-01-01T08:00:04.000+08:00|    d1|   2| 2.0|
|1970-01-01T08:00:05.000+08:00|    d1|   4| 6.0|
|1970-01-01T08:00:03.000+08:00|    d0|   1| 1.0|
|1970-01-01T08:00:00.000+08:00|    d0|   3| 7.0|
|1970-01-01T08:00:02.000+08:00|    d0|   3| 7.0|
|1970-01-01T08:00:01.000+08:00|    d0|   5|12.0|
+-----------------------------+------+----+----+- Query all original columns from the device_flow table, group the data by the device dimension (device), sort the records within each device group by the value of the flow field, count the number of rows within the range of "the flow group of the current row + the previous 1 flow group", and finally return the count result as a column named count.
SQL:
IoTDB> SELECT *, count(flow) OVER(PARTITION BY device ORDER BY flow GROUPS BETWEEN 1 PRECEDING AND CURRENT ROW) as count FROM device_flow;Result:
+-----------------------------+------+----+-----+
|                         time|device|flow|count|
+-----------------------------+------+----+-----+
|1970-01-01T08:00:04.000+08:00|    d1|   2|    1|
|1970-01-01T08:00:05.000+08:00|    d1|   4|    2|
|1970-01-01T08:00:03.000+08:00|    d0|   1|    1|
|1970-01-01T08:00:00.000+08:00|    d0|   3|    3|
|1970-01-01T08:00:02.000+08:00|    d0|   3|    3|
|1970-01-01T08:00:01.000+08:00|    d0|   5|    3|
+-----------------------------+------+----+-----+- Query all original columns from the device_flow table, group the data by device, sort the records in ascending order by the value of the flow field within each group, count the number of all rows falling within the numeric range of "the flow value of the current row minus 2" to "the flow value of the current row", and finally return the count result as a column named count.
SQL:
IoTDB> SELECT *,count(flow) OVER(PARTITION BY device ORDER BY flow RANGE BETWEEN 2 PRECEDING AND CURRENT ROW) as count FROM device_flow;Result:
+-----------------------------+------+----+-----+
|                         time|device|flow|count|
+-----------------------------+------+----+-----+
|1970-01-01T08:00:04.000+08:00|    d1|   2|    1|
|1970-01-01T08:00:05.000+08:00|    d1|   4|    2|
|1970-01-01T08:00:03.000+08:00|    d0|   1|    1|
|1970-01-01T08:00:00.000+08:00|    d0|   3|    3|
|1970-01-01T08:00:02.000+08:00|    d0|   3|    3|
|1970-01-01T08:00:01.000+08:00|    d0|   5|    3|
+-----------------------------+------+----+-----+
5. Object Type Read Function
Description:
Reads binary content from an OBJECT type column and returns a BLOB type (raw binary data of the object).
Supported since V2.0.8
Syntax:
READ_OBJECT(object [, offset, length])Parameters:
- Required:
object(OBJECT type) - Optional:
offset(long/INT64): Start position for reading. Default:0.- Throws error if
offset < 0oroffset >= full file length.
- Throws error if
length(long/INT64): Number of bytes to read. Default: full file length.- Error if
length > 2^31 - 1. - If
lengthexceeds remaining bytes fromoffset, reads until end of file. - If
length < 0, reads all remaining data fromoffset.
- Error if
Examples:
IoTDB:database1> SELECT READ_OBJECT(s1) FROM table1 WHERE device_id = 'tag1'
+------------+
|       _col0|
+------------+
|0x696f746462|
+------------+
Total line number = 1

IoTDB:database1> SELECT READ_OBJECT(s1, 0, 3) FROM table1 WHERE device_id = 'tag1'
+--------+
|   _col0|
+--------+
|0x696f74|
+--------+
Total line number = 1
6. read_tsfile Table Function
6.1 Description
read_tsfile reads table-model data from external TsFile files or directories and returns a temporary table source. You can use SELECT, WHERE, ORDER BY, LIMIT, OFFSET, and aggregation as you would with an ordinary table for read-only analysis and temporary processing. Results are not written back to the external TsFiles, and internal IoTDB data is not modified. This function does not support writing, deleting, modifying, or registering external TsFiles.
Supported since V2.0.12.1
6.2 Function Definition
SELECT *
FROM TABLE(
  read_tsfile(
    TABLE_NAME => '<table_name>',
    PATHS => '<tsfile_or_directory_path>'
  )
);
6.3 Parameters
| Parameter | Required | Description |
|---|---|---|
PATHS | Yes | Path to a TsFile or directory. Pass a single path as a string. For multiple paths, separate them with commas within the same string, for example '/data/a.tsfile,/data/b.tsfile,/data/history'.- For a file path, the system attempts to open the file directly. - For a directory, the system recursively scans files with the .tsfile suffix and identifies valid TsFiles by the magic numbers at the beginning and end of each file. Files that are unrecognized, incomplete, not in TsFile format, or not TsFile V4 are excluded from the query.Paths must be visible to the DataNode process executing the query, and that process must have read permission. Specifying any DataNode data directory causes the query to fail. |
TABLE_NAME | No | Name of the table to read. When specified, only valid files containing the target table's schema are read. If none of the valid files contains that schema, the query fails. You can omit this argument when the table name can be inferred uniquely: every valid file to be read must contain exactly one table, and the inferred table name must be the same in all files. The query fails if a valid file contains multiple tables or if the unique table names differ between valid files. |
DEVICE_METADATA_INFO_SWAP_THRESHOLD | No | When both the number of files and the number of devices are large, some metadata may be written to temporary swap files to limit memory use. This Long value sets the size threshold that forces a swap. The default is 8 MB. |
Schema Merging Rules
When reading multiple TsFiles, the system determines the target table and merges its schemas. The merged schema is used only as the output schema for the current query and is not registered in database metadata. The rules are:
- TAG columns are merged in order and must have consistent prefixes. Different TAG names at the same position cause an error; additional TAG columns may be appended at later positions.
- The time-column name must be consistent across files; conflicting names cause an error.
- FIELD column order does not matter. Files can contain different FIELD columns, which are merged incrementally. FIELD columns with the same name must have compatible data types; otherwise, an error is reported.
- Columns with the same name in different TsFiles must have the same column category; otherwise, an error is reported.
Returned Results
- Returns the data of the specified table.
- Output columns come from the merged schema of the target table in the external TsFiles.
- The time column uses the time-column name recorded in the TsFiles.
- TAG columns represent device identifiers.
- FIELD columns contain measurement data.
6.4 Usage Examples
Assume /data/backup/1.tsfile exists and contains the metadata and data of table1 from Sample Data.
Example 1: Infer the Table Name
This example requires /data/backup/1.tsfile to contain exactly one table.
SELECT *
FROM TABLE(
  read_tsfile(
    PATHS => '/data/backup/1.tsfile'
  )
)
LIMIT 10;
Result:
+-----------------------------+------+--------+---------+--------+-----------+-----------+--------+------+-----------------------------+
|                         time|region|plant_id|device_id|model_id|maintenance|temperature|humidity|status|                 arrival_time|
+-----------------------------+------+--------+---------+--------+-----------+-----------+--------+------+-----------------------------+
|2024-11-29T10:00:00.000+08:00|  上海|    3001|      101|       D|        360|       85.0|    null|  null|2024-11-29T10:00:13.000+08:00|
|2024-11-29T11:00:00.000+08:00|  上海|    3002|      100|       E|        180|       null|    45.1|  true|                         null|
|2024-11-29T18:30:00.000+08:00|  上海|    3002|      100|       E|        180|       90.0|    35.4|  true|2024-11-29T18:30:15.000+08:00|
|2024-11-30T09:30:00.000+08:00|  上海|    3002|      101|       F|        360|       90.0|    35.2|  true|                         null|
|2024-11-30T14:30:00.000+08:00|  上海|    3002|      101|       F|        360|       90.0|    34.8|  true|2024-11-30T14:30:17.000+08:00|
|2024-11-26T13:37:00.000+08:00|  北京|    1001|      100|       A|        180|       90.0|    35.1|  true|2024-11-26T13:37:34.000+08:00|
|2024-11-26T13:38:00.000+08:00|  北京|    1001|      100|       A|        180|       90.0|    35.1|  true|2024-11-26T13:38:25.000+08:00|
|2024-11-28T08:00:00.000+08:00|  上海|    3001|      100|       C|         90|       85.0|    null|  null|2024-11-28T08:00:09.000+08:00|
|2024-11-28T09:00:00.000+08:00|  上海|    3001|      100|       C|         90|       null|    40.9|  true|                         null|
|2024-11-28T10:00:00.000+08:00|  上海|    3001|      100|       C|         90|       85.0|    35.2|  null|2024-11-28T10:00:11.000+08:00|
+-----------------------------+------+--------+---------+--------+-----------+-----------+--------+------+-----------------------------+
Total line number = 10
It costs 0.159s
Example 2: Read TsFiles from a Directory
SELECT time, device_id, temperature
FROM TABLE(
  read_tsfile(
    TABLE_NAME => 'table1',
    PATHS => '/data/backup'
  )
)
WHERE time >= 2024-11-28 00:00:00 AND time < 2024-11-29 00:00:00 ;
Result:
+-----------------------------+---------+-----------+
|                         time|device_id|temperature|
+-----------------------------+---------+-----------+
|2024-11-28T08:00:00.000+08:00|      100|       85.0|
|2024-11-28T09:00:00.000+08:00|      100|       null|
|2024-11-28T10:00:00.000+08:00|      100|       85.0|
|2024-11-28T11:00:00.000+08:00|      100|       88.0|
+-----------------------------+---------+-----------+
Total line number = 4
It costs 0.116s
Example 3: Aggregate by TAG
SELECT device_id, count(temperature)
FROM TABLE(
  read_tsfile(
    TABLE_NAME => 'table1',
    PATHS => '/data/backup'
  )
)
GROUP BY device_id;
Result:
+---------+-----+
|device_id|_col1|
+---------+-----+
|      100|    6|
|      101|    6|
+---------+-----+
Total line number = 2
It costs 0.049s
7. Time-Series Trend Matching Table Function
7.1 Description
The pattern_match table function searches a historical time series for subsequences that match an input pattern sequence and returns all matches satisfying the specified threshold, result bounds, and other conditions.
Supported since V2.0.12.1
7.2 Function Definition
pattern_match(
  data => {table_name | subquery} PARTITION BY partition_col ORDER BY time_col,
  [time_col => 'time_column_name',]
  data_col => 'data_column_name',
  pattern => 'pattern_sequence',
  smooth => numeric_value,
  threshold => numeric_value,
  [width => numeric_value,]
  [height => numeric_value,]
  [smooth_on_pattern => {true | false}]
)
7.3 Parameters
| Parameter | Type | Required | Default | Description |
|---|---|---|---|---|
data | Table name or subquery | Yes | - | Table or subquery containing the time series. The time column must be ordered. Supports PARTITION BY for partitioning and ORDER BY for sorting by time. |
time_col | String | No | 'time' | Name of the time column. Only the TIMESTAMP type is supported. |
data_col | String | Yes | - | Name of the series column. Supported types: INT32, INT64, DOUBLE, and FLOAT. |
pattern | String | Yes | - | Numeric sequence to match, supporting ordinary trend sequences and regular-expression rules: 1. Basic format: comma-separated integers or floating-point values, such as '1.0,2.0,3.0'.2. Regular-expression extensions: {segment}+ repeats a segment at least once, and {segment}* repeats it zero or more times. {, }*, and }+ are separate units.3. The leftmost point of each segment is shared with the preceding segment. |
smooth | Non-negative real number | Yes | - | Tolerance for fluctuations (smoothing level). Larger values tolerate greater fluctuations but may oversmooth normal data. A recommended starting value is 1% of the value range; adjust it to the series. |
threshold | Non-negative real number | Yes | - | Similarity threshold. Only matches with a similarity value below this threshold are returned. Smaller values require a closer match. Start at 1 and increase as needed. |
width | Non-negative real number | No | Unlimited | Maximum width of a match. Only subsequences with a timestamp span below this value are returned. |
height | Non-negative real number | No | Unlimited | Maximum height of a match. Only subsequences with a height below this value are returned. |
smooth_on_pattern | Boolean | No | false | Whether to smooth the pattern: 1. false: treats the pattern as a trend shape and smooths only the original series.2. true: applies the same smoothing and noise reduction to both the pattern and the original series. |
Returned Results
Only rows belonging to matching segments are retained, in ascending match_index order. Unmatched rows are discarded.
| Column | Type | Description |
|---|---|---|
match_index | INT32 | Non-negative integer identifying the matched segment. |
similarity | DOUBLE | Non-negative similarity value for the segment and pattern. Smaller values indicate closer matches. |
All columns from data | Same as input | Original data from all columns of the input data argument. |
7.4 Usage Examples
The following examples demonstrate basic pattern matching, parameter adjustment, regular-expression patterns, and smoothing.
7.4.1 Prepare Test Data
Create a table and insert data:
create table test(value DOUBLE FIELD, value1 DOUBLE FIELD);
INSERT INTO test VALUES (1, 1, 0),(2, 2, 0),(3, 1, 0),(4, 1, 0),(5, 1, 0),(6, 1.2, 0),(7, 1, 0),(8, 1, 0),(9, 2, 0),(10, 3, 0),(11, 4, 0),(12, 3, 0),(13, 2, 0),(14, 3, 0),(15, 4, 0),(16, 2, 0),(17, 1, 0),(18, 1, 0),(19, 1, 0),(20, 1, 0),(21, 1, 0),(41, 1, 0),(42, 2, 0),(43, 3, 0),(44, 4, 0),(45, 3, 0),(46, 2, 0),(47, 2, 0),(48, 2, 0),(49, 2, 0),(50, 2, 0),(51, 2, 0),(52, 2, 0);
Query the data:
select * from test;The data is shown below:
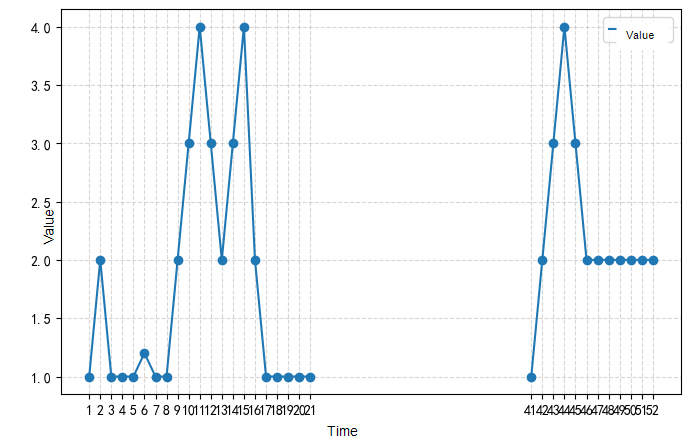
7.4.2 Basic Trend Matching
Use an ordinary sequence as the pattern to find subsequences with a similar trend.
select * from pattern_match(
  data => test ORDER BY time,
  time_col => 'time',
  data_col => 'value',
  pattern => '1.0,2.0,3.0,2.0,1.0,1.0,1.0,1.0,1.0',
  smooth => 0.5,
  threshold => 10.0,
  width => 1000.0,
  height => 500.0,
  smooth_on_pattern=> false
);
The matching results are shown below:
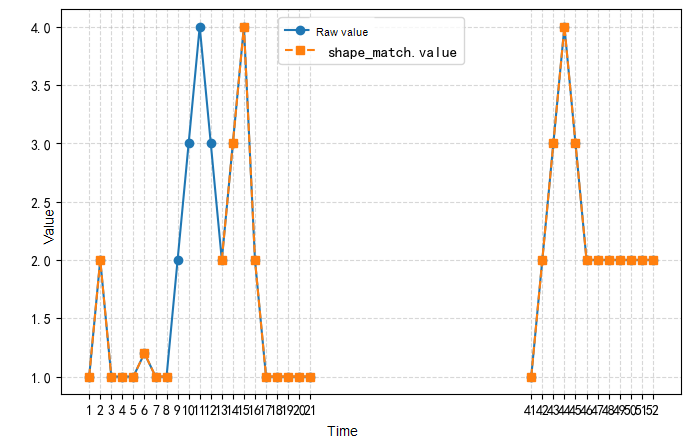
The query returns 3 matching segments. A smaller similarity value indicates a closer match.
+-----------+------------------+-----------------------------+-----+------+
|match_index|        similarity|                         time|value|value1|
+-----------+------------------+-----------------------------+-----+------+
|          0| 4.637180787192477|1970-01-01T08:00:00.001+08:00|  1.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.002+08:00|  2.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.003+08:00|  1.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.004+08:00|  1.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.005+08:00|  1.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.006+08:00|  1.2|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.007+08:00|  1.0|   0.0|
|          0| 4.637180787192477|1970-01-01T08:00:00.008+08:00|  1.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.013+08:00|  2.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.014+08:00|  3.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.015+08:00|  4.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.016+08:00|  2.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.017+08:00|  1.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.018+08:00|  1.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.019+08:00|  1.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.020+08:00|  1.0|   0.0|
|          1|0.6465473220616865|1970-01-01T08:00:00.021+08:00|  1.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.041+08:00|  1.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.042+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.043+08:00|  3.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.044+08:00|  4.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.045+08:00|  3.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.046+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.047+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.048+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.049+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.050+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.051+08:00|  2.0|   0.0|
|          2| 0.679768727042932|1970-01-01T08:00:00.052+08:00|  2.0|   0.0|
+-----------+------------------+-----------------------------+-----+------+
Total line number = 29
It costs 0.126s
7.4.3 Adjust Matching Conditions
Each example below starts from the query in Section 7.4.2 and changes only the indicated argument.
| Purpose | Parameter | Original Value | New Value | Effect |
|---|---|---|---|---|
| Require a closer match | threshold | 10.0 | 1.0 | Retains only results with similarity below 1.0, reducing the number of matching segments from 3 to 2. |
| Limit the time span | width | 1000.0 | 10.0 | Returns only subsequences with a timestamp span below 10.0. |
| Limit the value range | height | 500.0 | 2.0 | Returns only subsequences with a value range below 2.0. |
7.4.4 Regular-Expression Patterns
Regular-expression patterns can match repeated trend segments.
| Repetition Symbol | Meaning |
|---|---|
+ | The preceding subsequence occurs at least once. |
* | The preceding subsequence occurs zero or more times. |
The following example uses + to match one or more occurrences of 2.0,3.0,2.0:
select * from pattern_match(
  data              => test ORDER BY time,
  time_col          => 'time',
  data_col          => 'value',
  pattern           => '1.0,{2.0,3.0,2.0}+,1.0,1.0,1.0,1.0,1.0',
  smooth            => 0.5,
  threshold         => 100.0,
  width             => 1000.0,
  height            => 500.0,
  smooth_on_pattern => false
);
To allow zero or more occurrences of 2.0,3.0,2.0, replace + with *:
pattern => '1.0,{2.0,3.0,2.0}*,1.0,1.0,1.0,1.0,1.0'Regular-expression patterns are useful for periodic fluctuations, repeated peaks, and trend matches of variable length.
7.4.5 Pattern Smoothing
When the pattern contains small fluctuations, use smooth_on_pattern to control whether the pattern is also smoothed.
The following examples show the results of two configurations:
| Configuration | threshold | smooth_on_pattern | Matching Behavior |
|---|---|---|---|
| Smooth both the original series and the pattern | 1.0 | true | Matches the 1.0,1.2,1.0 fluctuation in the original data. |
| Smooth only the original series | 10.0 | false | Returns other trend matches but excludes the corresponding 1.0,1.2,1.0 fluctuation. |
Smooth both the original series and the pattern:
SELECT *
FROM pattern_match(
  data              => test ORDER BY time,
  time_col          => 'time',
  data_col          => 'value',
  pattern           => '1.0,1.2,1.0',
  smooth            => 0.5,
  threshold         => 1.0,
  width             => 1000.0,
  height            => 500.0,
  smooth_on_pattern => true
);
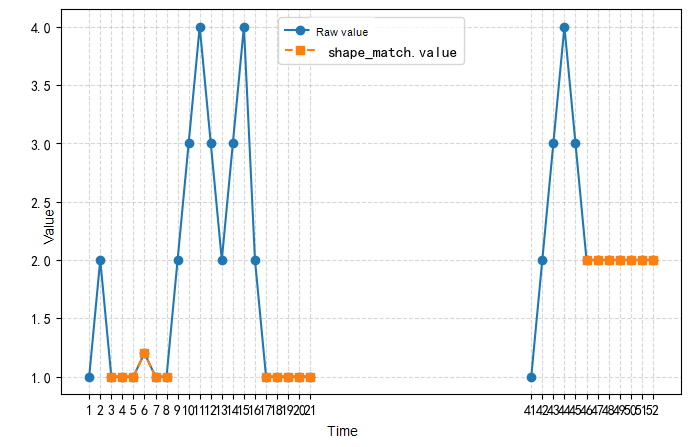
With the same smoothing rules applied to both sequences, the query matches the 1.0,1.2,1.0 fluctuation at time points 5, 6, and 7.
The results are shown below:
Smooth only the original series:
SELECT *
FROM pattern_match(
  data              => test ORDER BY time,
  time_col          => 'time',
  data_col          => 'value',
  pattern           => '1.0,1.2,1.0',
  smooth            => 0.5,
  threshold         => 10.0,
  width             => 1000.0,
  height            => 500.0,
  smooth_on_pattern => false
);
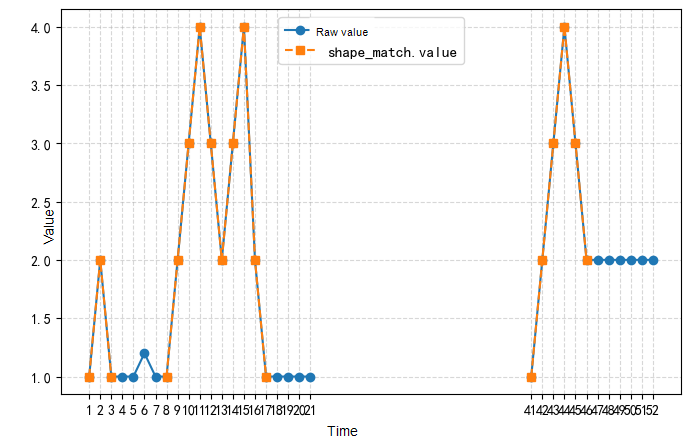
With smoothing applied only to the original series, the query still returns other trend matches, but the 1.0,1.2,1.0 fluctuation at time points 5, 6, and 7 is not matched.
The results are shown below:
8. Frequency-Domain Analysis Functions
8.1 FFT
8.1.1 Description
FFT is a built-in table function in the table model. It performs a one-dimensional fast Fourier transform on one or more real-valued numeric series in each input partition. ORDER BY must specify the time column in ascending order. You can also use PARTITION BY to group data by device or TAG. Each partition generates its own frequency bins, and all numeric columns in the partition share the same frequency axis.
Supported since V2.0.12.1
8.1.2 Function Definition
Named-argument syntax:
SELECT *
FROM FFT(
  DATA => {table_name | subquery}
    [PARTITION BY partition_column [, ...]]
    ORDER BY time_column,
  [SAMPLE_INTERVAL => duration_literal,]
  [N => positive_integer,]
  [NORM => {'backward' | 'forward' | 'ortho'},]
  [TIMECOL => 'time_column']
);
Positional-argument syntax:
SELECT *
FROM TABLE(
  FFT(
    TABLE(table_name)
      [PARTITION BY partition_column [, ...]]
      ORDER BY time_column
    [, duration_literal
    [, positive_integer
    [, norm
    [, time_column_name]]]]
  )
);
The canonical argument order is DATA, SAMPLE_INTERVAL, N, NORM, TIMECOL. Named arguments are recommended to make complex calls easier to read.
8.1.3 Parameters
| Parameter | Required | Type | Default | Description |
|---|---|---|---|---|
DATA | Yes | Table argument | None | Input data for FFT. With PARTITION BY, each partition is calculated independently; without it, all input rows form one partition. All INT32, INT64, FLOAT, and DOUBLE columns except the time and partition columns participate in the calculation. Other column types are ignored. At least one numeric column is required, and participating columns cannot contain NULL. To transform only selected numeric columns, project them in an input subquery. |
SAMPLE_INTERVAL | No | Positive duration literal | Inferred from the time column | Sampling interval used to calculate the frequency axis, such as 1ms, 10ms, or 1s. If omitted, it is inferred per partition as (last timestamp - first timestamp) / (input row count - 1). A single-row partition requires an explicit interval; an empty partition returns 0 rows. |
N | No | Positive integer | Input row count of the current partition | FFT length. If smaller than the input row count, only the first N rows in timestamp order are transformed. If larger, the series is padded with zeros at the end. Each partition returns N rows. The maximum N is 65536, and N × 2 × number of participating numeric columns ≤ 16777216 must hold. |
NORM | No | String | backward | Normalization mode, case-insensitive. backward: no normalization; forward: divide by N; ortho: divide by √N. |
TIMECOL | No | String | time | Name of the time column, which must have type TIMESTAMP. DATA must be sorted only by this column in ascending order; DESC is unsupported. Timestamps within each partition must be strictly increasing, with no duplicates. |
- FFT is generally intended for evenly sampled data. This function does not automatically detect or correct irregular sampling. Interpolate or resample the data before calculation to ensure accurate spectra. If the sampling interval is known, explicitly set
SAMPLE_INTERVAL. - When
Nis smaller than the input row count, the function still validates all input rows in the partition, although only the firstNrows are transformed.
Returned Results
FFT returns the full two-sided spectrum for each partition, with columns in the following order:
partition_columns...
frequency_index
frequency
<numeric_column>_real
<numeric_column>_imag
...| Output Column | Type | Description |
|---|---|---|
Columns specified by PARTITION BY | Same as input | Retain their original names and types and appear first in the result. Omitted when PARTITION BY is not used. |
frequency_index | INT64 | Frequency-bin index, from 0 to N-1. |
frequency | DOUBLE | Frequency of the current bin, in Hz. |
<numeric_column>_real | DOUBLE | Real part of the FFT for the corresponding numeric input column. |
<numeric_column>_imag | DOUBLE | Imaginary part of the FFT for the corresponding numeric input column. |
For transform length N and sampling interval d in seconds, frequency is calculated as follows:
frequency_index Range | frequency |
|---|---|
frequency_index < ceil(N / 2) | frequency_index / (N × d) |
| Otherwise | (frequency_index - N) / (N × d) |
Frequencies are ordered as zero, positive, then negative frequencies, in Hz. All numeric columns within a partition share the same frequency axis.
8.1.4 Notes
- The function name
FFTis case-insensitive. Each partition performs a separate one-dimensional FFT. - The current version supports only real-valued input. Complex input,
DFT, andIFFTare unsupported. - The current version returns only the real and imaginary parts of the full spectrum. One-sided spectra, amplitude output, and phase output are unsupported.
- The
VALUE,SAMPLE_RATE, andSPECTRUMarguments are unsupported in the current version.
8.1.5 Usage Examples
These examples use table1. Because temperature contains NULL values, filter them out in the input subquery.
Example 1: FFT by Device
SELECT *
FROM FFT(
  DATA => (
    SELECT time, device_id, temperature
    FROM table1
    WHERE plant_id = '1001'
      AND temperature IS NOT NULL
  ) PARTITION BY device_id ORDER BY time
)
ORDER BY device_id, frequency_index;
The function transforms temperature separately for each device. With N and SAMPLE_INTERVAL omitted, the transform length is the input row count of each partition, and the sampling interval is inferred from the time column. In this example, the sampling interval is 1 minute.
+---------+---------------+---------------------+----------------------+---------------------+
|device_id|frequency_index|            frequency|      temperature_real|     temperature_imag|
+---------+---------------+---------------------+----------------------+---------------------+
|      100|              0|                  0.0|                 180.0|                  0.0|
|      100|              1|-0.008333333333333333|                   0.0|                  0.0|
|      101|              0|                  0.0|                 255.0| -6.67572021484375E-6|
|      101|              1| 0.005555555555555556|-4.6126147026370745E-6|-5.266308107820805E-6|
|      101|              2|-0.005555555555555556|   -1.9073486328125E-6| 3.303624680484063E-6|
+---------+---------------+---------------------+----------------------+---------------------+
Example 2: Specify Transform Length and Normalization
SELECT *
FROM FFT(
  DATA => (
    SELECT time, device_id, temperature
    FROM table1
    WHERE plant_id = '1001'
      AND temperature IS NOT NULL
  ) PARTITION BY device_id ORDER BY time,
  SAMPLE_INTERVAL => 1m,
  N => 4,
  NORM => 'ortho'
)
ORDER BY device_id, frequency_index;
The transform length is set to 4 for each device. Series with fewer than 4 input rows are padded with zeros at the end. FFT results are normalized by 1/√N. Each device returns 4 spectrum rows.
+---------+---------------+---------------------+----------------------+----------------+
|device_id|frequency_index|            frequency|      temperature_real|temperature_imag|
+---------+---------------+---------------------+----------------------+----------------+
|      100|              0|                  0.0|                  90.0|             0.0|
|      100|              1| 0.004166666666666667|                  45.0|           -45.0|
|      100|              2|-0.008333333333333333|                   0.0|             0.0|
|      100|              3|-0.004166666666666667|                  45.0|            45.0|
|      101|              0|                  0.0|                 127.5|             0.0|
|      101|              1| 0.004166666666666667| 2.602374475716698E-15|           -42.5|
|      101|              2|-0.008333333333333333|                  42.5|             0.0|
|      101|              3|-0.004166666666666667|-2.602374475716698E-15|            42.5|
+---------+---------------+---------------------+----------------------+----------------+
Example 3: Numeric Column Contains NULL
SELECT *
FROM FFT(
  DATA => (
    SELECT time, device_id, temperature
    FROM table1
    WHERE plant_id = '1001'
  ) PARTITION BY device_id ORDER BY time
);
The query fails because numeric columns participating in FFT cannot contain NULL:
Msg: org.apache.iotdb.jdbc.IoTDBSQLException: 701: FFT does not support null values in column [temperature].Filter out null values with IS NOT NULL in the input subquery before running FFT.
8.2 lowPass
8.2.1 Description
lowPass is a low-pass filter that applies frequency-domain filtering to numeric columns in the input table. It retains low-frequency components and attenuates high-frequency components, making it useful for signal smoothing and high-frequency noise removal. The normalized passband frequency wpass, in the range (0, 1), specifies the upper frequency bound of the passband.
Supported since V2.0.12.1
8.2.2 Function Definition
Named-argument syntax:
SELECT *
FROM lowPass(
  DATA => input_table PARTITION BY partition_column ORDER BY time_column,
  TIMECOL => 'time_column',
  WPASS => passband_frequency
);
Positional-argument syntax:
SELECT *
FROM lowPass(
  input_table PARTITION BY partition_column ORDER BY time_column,
  'time_column',
  passband_frequency
);
8.2.3 Parameters
| Parameter | Type | Required | Description |
|---|---|---|---|
DATA | Table argument (SET SEMANTIC) | Yes | Input table or subquery. ORDER BY must contain only the time column in ascending order. PARTITION BY is optional; if omitted, the entire table is treated as one partition. |
TIMECOL | String | Yes | Name of the time column. Must identify exactly one column of type TIMESTAMP. |
WPASS | DOUBLE | Yes | Normalized passband frequency in (0, 1). Components below this frequency are retained, and those above it are attenuated. |
Calculation Rules
- Columns specified by
TIMECOLandPARTITION BYare excluded from calculations but retained in the output. - Apart from the time and partition columns, only
INT32,INT64,FLOAT, andDOUBLEcolumns can participate. Analysis fails if no eligible column remains or if any other column type is present. NULLvalues in a participating column are excluded from that column's filtering calculation.
Returned Results
- The output includes the partition columns, if specified, and the time column, with their original names and types.
- Each participating numeric column produces a filtered result column of type
DOUBLE. Each result column has the same number of points as its corresponding input column, output in ascending timestamp order.
8.2.4 Usage Example
The following example uses table1.
SELECT *
FROM lowPass(
  DATA => (
     SELECT time, device_id, temperature
     FROM table1
     WHERE temperature is not null
  ) PARTITION BY device_id  ORDER BY time,
  TIMECOL => 'time',
  WPASS => 0.3
);
The example partitions data by device, applies low-pass filtering to temperature, and returns device_id, time, and the filtered numeric column.
+---------+-----------------------------+--------------------+
|device_id|                         time|lowpass(temperature)|
+---------+-----------------------------+--------------------+
|      100|2024-11-26T13:37:00.000+08:00|                88.0|
|      100|2024-11-26T13:38:00.000+08:00|                88.0|
|      100|2024-11-28T08:00:00.000+08:00|   87.99999999999999|
|      100|2024-11-28T10:00:00.000+08:00|   87.99999999999999|
|      100|2024-11-28T11:00:00.000+08:00|   88.00000000000001|
|      100|2024-11-29T18:30:00.000+08:00|                88.0|
|      101|2024-11-27T16:39:00.000+08:00|   86.66666666666667|
|      101|2024-11-27T16:40:00.000+08:00|   86.66666666666667|
|      101|2024-11-27T16:41:00.000+08:00|   86.66666666666664|
|      101|2024-11-29T10:00:00.000+08:00|   86.66666666666664|
|      101|2024-11-30T09:30:00.000+08:00|   86.66666666666667|
|      101|2024-11-30T14:30:00.000+08:00|   86.66666666666664|
+---------+-----------------------------+--------------------+
8.3 highPass
8.3.1 Description
highPass is a high-pass filter that applies frequency-domain filtering to numeric columns in the input table. It retains high-frequency components and attenuates low-frequency components, making it useful for extracting rapid changes, abrupt transitions, and high-frequency noise. The normalized passband frequency wpass, in the range (0, 1), specifies the lower frequency bound of the passband.
Supported since V2.0.12.1
8.3.2 Function Definition
Named-argument syntax:
SELECT *
FROM highPass(
  DATA => input_table PARTITION BY partition_column ORDER BY time_column,
  TIMECOL => 'time_column',
  WPASS => passband_frequency
);
Positional-argument syntax:
SELECT *
FROM highPass(
  input_table PARTITION BY partition_column ORDER BY time_column,
  'time_column',
  passband_frequency
);
8.3.3 Parameters
| Parameter | Type | Required | Description |
|---|---|---|---|
DATA | Table argument (SET SEMANTIC) | Yes | Input table or subquery. ORDER BY must contain only the time column in ascending order. PARTITION BY is optional; if omitted, the entire table is treated as one partition. |
TIMECOL | String | Yes | Name of the time column. Must identify exactly one column of type TIMESTAMP. |
WPASS | DOUBLE | Yes | Normalized passband frequency in (0, 1). Components above this frequency are retained, and those below it are attenuated. |
Input Columns and Calculation Rules
- Columns specified by
TIMECOLandPARTITION BYare excluded from calculations but retained in the output. - Apart from the time and partition columns, only
INT32,INT64,FLOAT, andDOUBLEcolumns can participate. Analysis fails if no eligible column remains or if any other column type is present. NULLvalues in a participating column are excluded from that column's filtering calculation.
Returned Results
- The output includes the partition columns, if specified, and the time column, with their original names and types.
- Each participating numeric column produces a filtered result column of type
DOUBLE. Each result column has the same number of points as its corresponding input column, output in ascending timestamp order.
8.3.4 Usage Example
SELECT *
FROM highPass(
  DATA => (
     SELECT time, device_id, temperature
     FROM table1
     WHERE temperature is not null
  ) PARTITION BY device_id  ORDER BY time,
  TIMECOL => 'time',
  WPASS => 0.3
);
The example partitions data by device, applies high-pass filtering to temperature, and returns device_id, time, and the filtered numeric column.
+---------+-----------------------------+----------------------+
|device_id|                         time| highpass(temperature)|
+---------+-----------------------------+----------------------+
|      100|2024-11-26T13:37:00.000+08:00|     2.000000000000029|
|      100|2024-11-26T13:38:00.000+08:00|     2.000000000000004|
|      100|2024-11-28T08:00:00.000+08:00|   -2.9999999999999702|
|      100|2024-11-28T10:00:00.000+08:00|    -3.000000000000013|
|      100|2024-11-28T11:00:00.000+08:00|-4.182831670630972E-14|
|      100|2024-11-29T18:30:00.000+08:00|    1.9999999999999953|
|      101|2024-11-27T16:39:00.000+08:00|    -1.666666666666642|
|      101|2024-11-27T16:40:00.000+08:00|   -1.6666666666666519|
|      101|2024-11-27T16:41:00.000+08:00|    -1.666666666666645|
|      101|2024-11-29T10:00:00.000+08:00|    -1.666666666666701|
|      101|2024-11-30T09:30:00.000+08:00|    3.3333333333333015|
|      101|2024-11-30T14:30:00.000+08:00|     3.333333333333338|
+---------+-----------------------------+----------------------+
9. Time-Series Correlation Analysis Functions
9.1 Xcorr
9.1.1 Description
Xcorr performs cross-correlation analysis on two numeric series to measure their shape similarity at different time lags. It shifts one series relative to the other, multiplies corresponding points, and sums the products to produce a similarity curve. This can reveal delays and similar patterns between two signals.
Supported since V2.0.12.1
9.1.2 Function Definition
Named-argument syntax:
SELECT *
FROM Xcorr(
  DATA => (
    SELECT time_column, signal_1, signal_2, partition_column
    FROM input_table
  ) PARTITION BY partition_column ORDER BY time_column,
  TIMECOL => 'time_column'
);
Positional-argument syntax:
SELECT *
FROM Xcorr(
    ( SELECT time_column, signal_1, signal_2, partition_column
      FROM input_table
    ) PARTITION BY partition_column ORDER BY time_column,
    'time_column'
);
9.1.3 Parameters
| Parameter | Type | Required | Description |
|---|---|---|---|
DATA | Table argument (SET SEMANTIC) | Yes | Input table or subquery. ORDER BY must specify the time column in ascending order. PARTITION BY is optional. Exactly two numeric columns must remain after excluding the time and partition columns. |
TIMECOL | String | Yes | Name of the time column. Must identify exactly one column of type TIMESTAMP. |
Calculation Rules
- The time and partition columns are excluded from cross-correlation calculations.
- Exactly two columns must remain after those columns are excluded. Both must be of type
INT32,INT64,FLOAT, orDOUBLE; otherwise, analysis fails. NULLvalues in either participating column are treated as0at that position.- Timestamps must be strictly increasing within each partition.
- Normalization is applied according to the function definition.
Returned Results
- Partition columns specified by
PARTITION BY, if any, retain their original names and types. - One result column of type
DOUBLEis generated for the two participating columns.
9.1.4 Usage Example
The following example uses table1 from the SQL manual's sample data. A subquery selects the two numeric series, temperature and humidity, for cross-correlation.
SELECT *
FROM Xcorr(
  DATA => (
    SELECT time, device_id, temperature, humidity
    FROM table1
    WHERE temperature IS NOT NULL
      AND humidity IS NOT NULL
  )
  PARTITION BY device_id
  ORDER BY time,
  TIMECOL => 'time'
);
The example partitions data by device, cross-correlates temperature and humidity, and returns device_id and the correlation result column.
+---------+----------------------------+
|device_id|xcorr(temperature, humidity)|
+---------+----------------------------+
|      100|          3186.0001373291016|
|      100|                      3622.5|
|      100|          3412.0000203450522|
|      100|          3318.9249839782715|
|      100|          3292.9599586486815|
|      100|          3324.7749156951904|
|      100|          3080.0999348958335|
|      100|          3123.8998641967773|
|      100|          3158.9998626708984|
|      101|          2957.9999351501465|
|      101|          3061.9999980926514|
|      101|           3100.166645050049|
|      101|                      3172.5|
|      101|           3176.999931335449|
+---------+----------------------------+